HUMAIN says its sovereign AI stack, led by a 3-trillion-parameter open-weight model, goes live on 15 December
The PIF-backed company says the model will be the largest ever released with open weights, and that it costs 88% less and uses 88% fewer tokens than models available outside Saudi Arabia. No model card, benchmark, licence or price has been published.
What happened
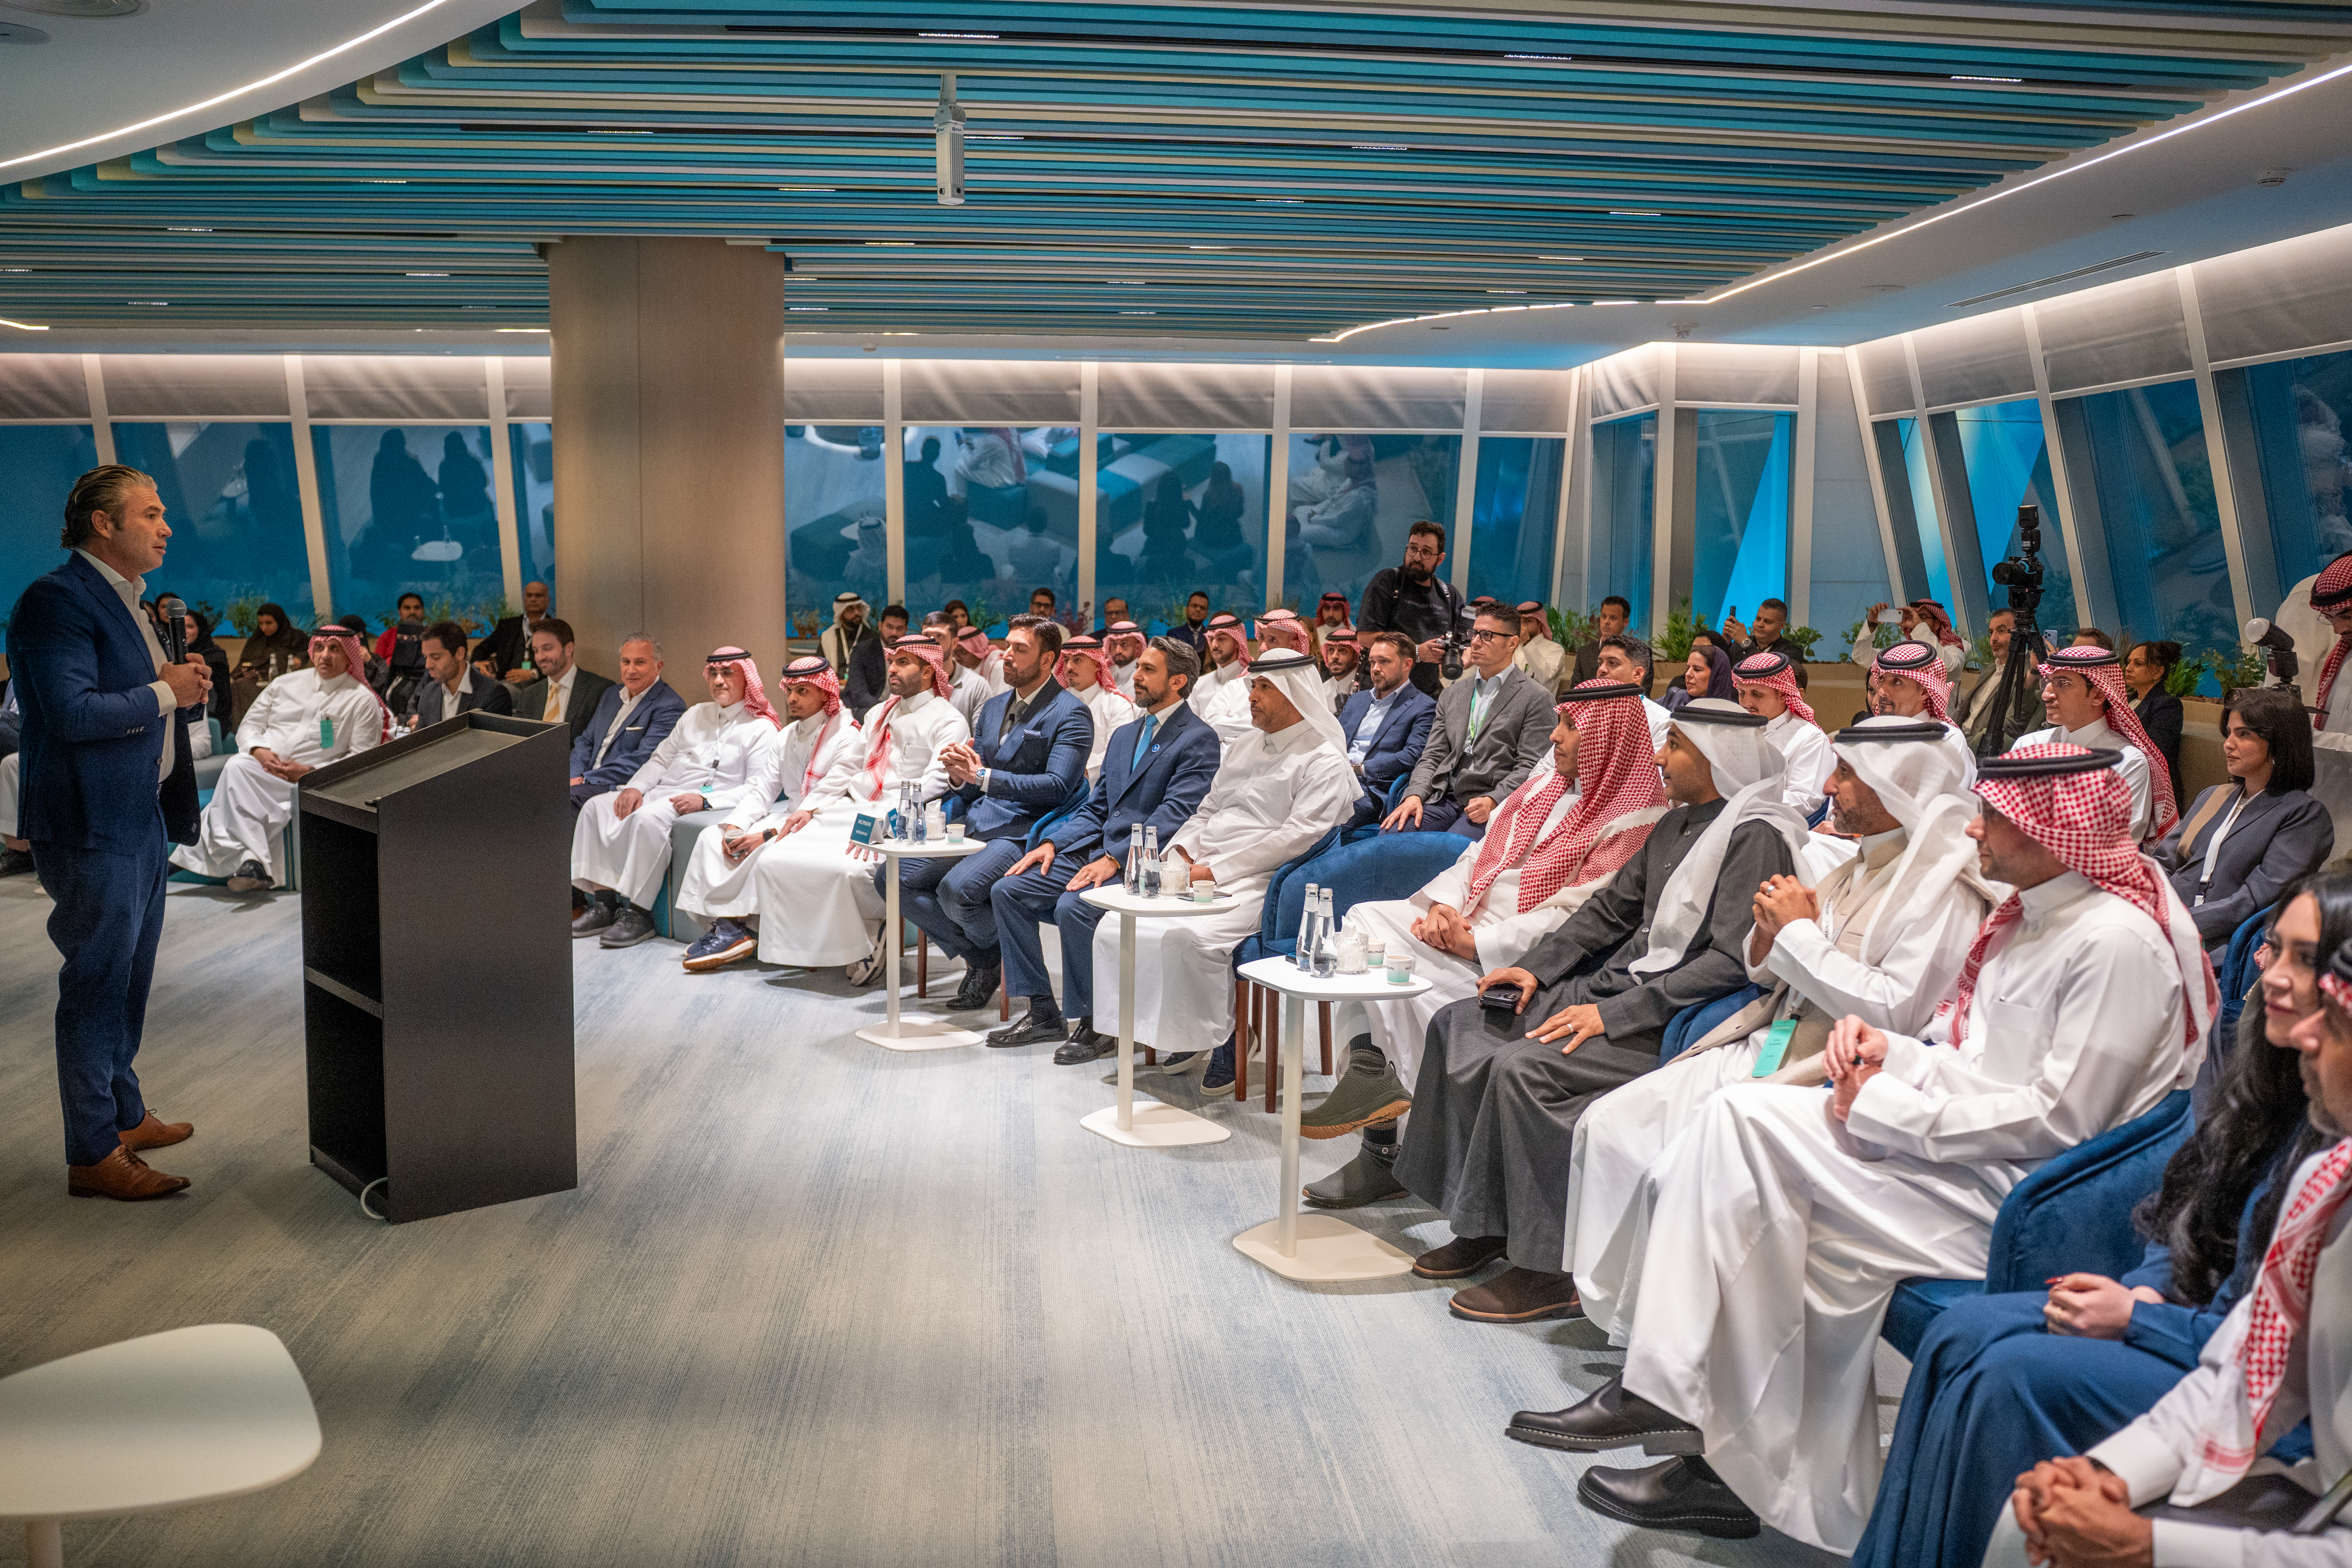
Summary of reporting by Arab NewsTareq Amin, chief executive of the PIF-backed company HUMAIN, told an audience at Majdoul Tower in Riyadh on 12 November that the company's complete AI stack becomes available inside Saudi Arabia on 15 December. The centrepiece is an unnamed open-weight model with 3 trillion parameters, which he described as the largest model ever developed and released with open weights, as Arab News reported.
HUMAIN claims the model costs 88% less and uses 88% fewer tokens than models available outside the Kingdom. None of those figures comes with a published benchmark, model card or third-party evaluation. The pitch is sovereignty: the model, the cloud inference service and the infrastructure underneath are built and run in-country, so data and operational control stay inside Saudi Arabia.
Amin said the stack took roughly 15 months to build; HUMAIN was set up in May 2025. He also confirmed HUMAIN+, an applied-AI training platform run with VUZ, offering about 1,500 learner places a year, which starts operating in Q1 2027. No price and no access route were announced at the event.
The gap is what matters for anyone planning a workload. Coverage from Middle East AI News and Nakoda raises the same open questions: the model card, the benchmarks and the pricing are all still to come. A parameter count on its own says nothing about whether a model is servable at your latency target or worth migrating for.
The Azrty take
A 3-trillion-parameter model would be the largest open-weight release yet, but the licence, the evals and the serving bill decide whether any GCC enterprise can actually use it.
For a CTO or head of AI in the Gulf, 15 December is a date to test, not a date to buy. The announcement gives a headline and a deadline but not the five things that decide whether a workload can move: a model card in the standard format, a licence you can sign, an active-parameter count and context window, a published price, and an independent evaluation. Within a week, board decks in Riyadh, Dubai and Doha will cite "3 trillion parameters" as a reason to wait or to switch. The useful counter is to have your own numbers ready, so you can answer in one meeting whether this beats what you run today on cost per completed task.
Two claims are worth separating. "3 trillion parameters" is a size claim, and size is easy to verify once weights or an API exist. "88% fewer tokens" is the one that decides your bill, and as stated it is not actionable. There are two very different explanations. If it is a tokeniser effect, the model packs the same text into fewer tokens, and you can settle it in an afternoon: run 10,000 of your own Arabic and English documents through both tokenisers and count. If it is a smaller reasoning budget, the model is spending less on thinking, which is a quality trade-off and will show up in your eval rather than your invoice. Do not let one number stand for both.
The sovereign framing needs a closer look too. "Built and run in-country" and "open weights" are separate commitments. The Open Source AI Definition is the reference here: it holds that an open model must ship the data information and the training code alongside the weights and parameters, and not only the parameters. HUMAIN describes its model line as "sovereign intelligence" and names ALLAM as its Arabic-first large language model, and neither that page nor the announcement carries a model card or licence text for the 3T system. Without a licence covering redistribution and model-as-a-service resale, you have a gated endpoint with a national label: a legitimate product, but not something you can host yourself. The serving arithmetic is the other half. A 3-trillion-parameter model at roughly 4 bits is about 1.5 TB of weights before a single byte of KV cache, so any self-hosted option is a multi-node deployment. DeepSeek-V3, an open-weight model at 671B parameters with 37B activated per token, is the useful comparison point (technical report); its own authors deploy the prefilling stage on 4 nodes and 32 GPUs. That cost lands in your inference price per unit of work whatever the per-token claim turns out to be.
So treat HUMAIN as one more upstream in a governed model gateway, not as a platform migration. An OpenAI-compatible gateway such as FastLLM Proxy puts routing, budgets and access control in one place. On the day the endpoint appears you register it with weight 0, and traffic shifts only when your evals justify it. Log prompts, outputs, token counts and cost per route to your own store: that is the audit trail a sovereign deployment is supposed to give you, and it also lets you test the 88% claim on your own traffic instead of on a slide.
# FastLLM Proxy route config, illustrative
routes:
  - name: reasoning-heavy
    upstreams:
      - id: humain-3t            # registered 15 Dec, weight 0 until evals pass
        base_url: ${HUMAIN_BASE_URL}
        weight: 0
        max_context: ${HUMAIN_MAX_CONTEXT}
      - id: current-primary
        base_url: ${PRIMARY_BASE_URL}
        weight: 100
    budgets:
      monthly_usd: 12000
      per_key_usd: 500
    fallback: current-primary
policies:
  log_prompts: true              # to your own store, 90-day retention
  data_residency: gcc-only
The opportunity is real and specific: Arabic-first tokenisation, in-region latency, and prompts and outputs that never leave a jurisdiction you control. No single US or Chinese API gives you all three cleanly today. Teams fail here in two directions: signing an enterprise agreement before a licence and an eval exist, or dismissing the whole thing as marketing and losing a year. The posture in between is to keep current models in production, stand the gateway and the eval harness up now, and treat 15 December as the first day you can collect evidence. Our team in the UAE does this work with clients: mapping what runs today, choosing the serving footprint, and putting the gateway and evaluations in place so model choice becomes an engineering decision with numbers behind it.
What to do now
- Build the eval set this week: 200 to 300 prompts taken from your own production traffic, roughly half Arabic and half English plus code, each with a gold answer and a scoring rubric. On 15 December, score HUMAIN against your current primary model on cost per completed task, not cost per token.
- Put an OpenAI-compatible gateway such as FastLLM Proxy in front of your current providers now. Register HUMAIN on 15 December as an upstream with weight 0, per-route budgets and one /v1/models list, so switching traffic is a YAML edit rather than a code change.
- Request five items in writing before any commercial talks: the model card, the full licence text (redistribution and model-as-a-service terms), active parameter count and context window, the tokeniser vocabulary, and a per-1M-token price for in-Kingdom and cross-border access.
- Test the 88% token claim yourself: run 10,000 representative Arabic and English documents through both tokenisers, count tokens and compute cost per document. Size the serving footprint as well: a 3T model at about 4 bits is roughly 1.5 TB of weights before any KV cache.