Infra and HUMAIN sign $667M of AI financing: 25 MW of GPUs now, grid designed for 1 GW
Two facilities under Infra's new AI Data Centre Financing Program convert about 56% of January's non-binding $1.2 billion framework. The split between silicon and grid tells you where the bottleneck is.
What happened
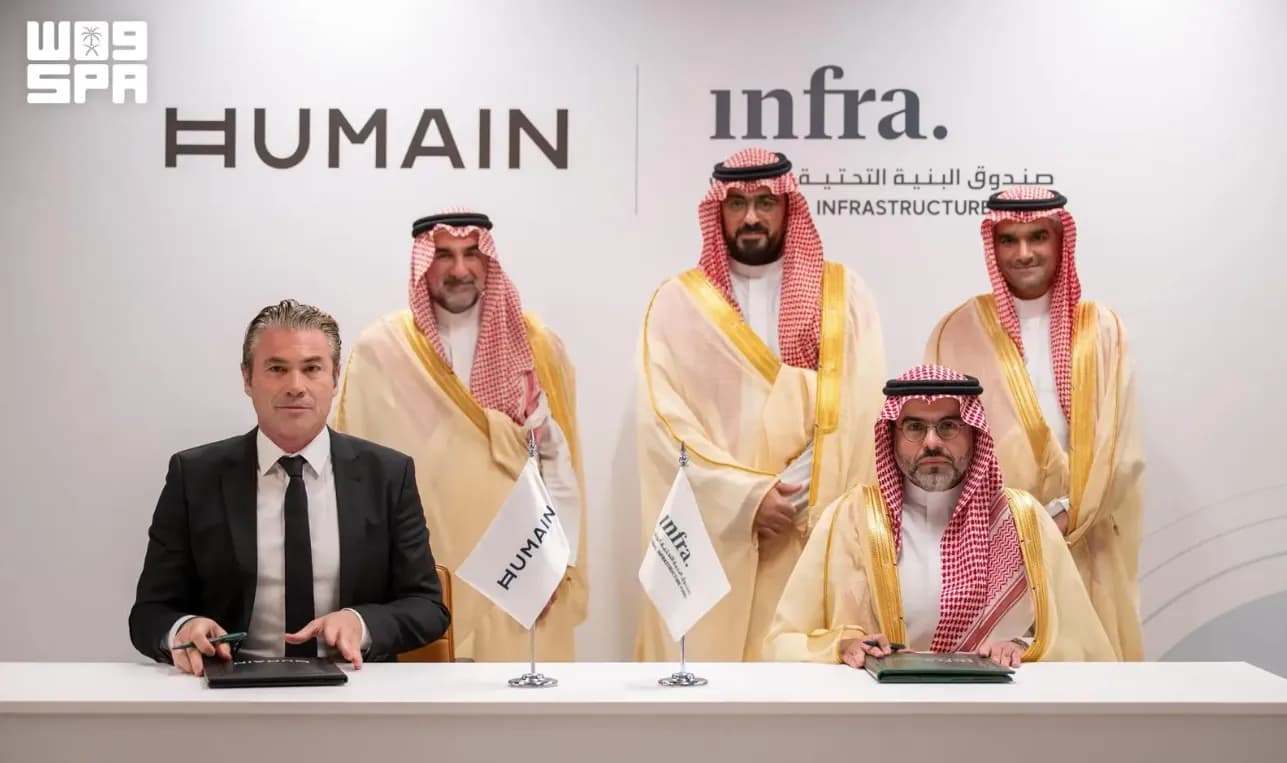
Summary of reporting by HUMAINOn 8 November 2026, Saudi Arabia's National Infrastructure Fund (Infra) and HUMAIN signed two financing agreements in Riyadh worth up to SAR 2.5 billion, about $667 million. They are the first transactions under Infra's new AI Data Centre Financing Program.
Together they convert roughly 56% of the non-binding SAR 4.5 billion ($1.2 billion) framework the two sides agreed at Davos in January 2026.
The two facilities split by layer. Up to SAR 1.1 billion (about $293.3 million) finances the procurement and deployment of GPUs representing roughly 25 MW of IT load. Up to SAR 1.4 billion (about $373.3 million) finances substations, transmission infrastructure and grid connections designed to support future development of up to 1 GW of IT capacity.
HUMAIN targets about 1 GW of AI data-centre capacity by 2027 and 6 GW by 2030. Its named backers and partners include AMD (about $10 billion), Nvidia, Qualcomm, Cisco, xAI and Together AI, and Aramco holds 49% of the company.
The Azrty take
Saudi's first AI-infrastructure debt is power-first: 25 MW of silicon now, grid designed for 1 GW. GCC buyers should price that gap, not the gigawatt headlines.
The $667 million headline matters less than the split. Of the SAR 2.5 billion, up to SAR 1.1 billion (about $293.3 million at 3.75 SAR to the dollar) buys GPUs for roughly 25 MW of IT load: about $11.7 million per MW of accelerator capacity. The larger facility, up to SAR 1.4 billion (about $373.3 million), funds substations, transmission and grid connections designed for future loads of up to 1 GW, or about $0.37 per watt of designed IT capacity in grid works alone. A state development financier has deliberately committed more money to power than to chips. For anyone budgeting AI compute in the UAE or the wider GCC, the binding constraint in this region is energisation, not accelerator supply. Read the deal as a construction sequence: 25 MW financed and deployable against 1 GW of grid designed-for. The number that matters in your contract is the substation energisation date and the megawatts attached to it, not the portfolio gigawatt in the press release.
HUMAIN's backing and its targets deserve the same discipline. Aramco holds 49% of the company, and the named backers and partners include AMD (about $10 billion), Nvidia, Qualcomm, Cisco, xAI and Together AI. HUMAIN's published target is about 1 GW of AI data-centre capacity by 2027 and 6 GW by 2030. Treat those as dated delivery schedules to verify, not as a portfolio you can plan against. The primary source is the HUMAIN announcement; regional coverage such as Middle East AI News tracks the same figures.
Where most teams will get it wrong: they book announced gigawatts as deliverable kilowatts, they pick a single vendor stack before benchmarking, and they finance GPUs without modelling refresh and residual value. Accelerators move on a 3 to 5 year cycle, and roughly $11.7 million per MW is a useful yardstick when you compare buying outright against leasing against reserved capacity. The 25 MW financed today against 1 GW of designed grid is not an inconsistency. It is the order of construction: power, then halls, then racks, then acceptance.
Technically, the approach we take at Azrty, from our base in Dubai, is portability from day one. Put one OpenAI-compatible gateway in front of every backend you will ever own or rent: your own GPU servers, a HUMAIN endpoint on AMD or Nvidia silicon, and hosted providers. Routing, budgets and access control belong in one place, and application code should depend on the gateway contract rather than a vendor SDK, so capacity arriving next quarter does not force a rewrite. Our FastLLM Proxy does exactly this, and our go-ai-sdk keeps the provider layer replaceable in Go. A minimal shape we recommend:
# FastLLM Proxy: one OpenAI-compatible endpoint, every backend behind it
providers:
  self-hosted: { base_url: "http://llm.internal/v1",     models: ["llama-3.3-70b-instruct"] }
  humain:      { base_url: "https://api.humain.com/v1",  models: ["<served-model>"] }
  hosted:      { base_url: "https://api.openai.com/v1",  models: ["gpt-4.1"] }
routing:
  default:  self-hosted
  fallback: [humain, hosted]
budgets:
  team-data: { monthly_usd: 6000, hard_stop: true }
  team-apps: { monthly_usd: 9000, hard_stop: false }
On the serving side, run the same weights under vLLM or SGLang on both architectures, size tensor parallelism to the rack, and hold gpu-memory-utilization around 0.90 to 0.92 so load can shift between pools as capacity lands. That portability is not theoretical. Both projects ship an OpenAI-compatible server and run on Nvidia and AMD hardware: SGLang's supported-hardware table lists AMD Instinct MI300X, MI325X, MI350X and MI355X alongside Nvidia B200, B300, GB200 and GB300, and vLLM documents support for Nvidia, AMD and Intel GPUs with tensor, pipeline, data, expert and context parallelism for distributed inference. So the silicon split inside this deal is a config choice, not an architectural fork. The opportunity for GCC organisations is real: cheaper, closer compute and financing structures that regional banks are likely to copy. The risk is paying today for capacity that exists only in a press release. Contract against power dates and keep the stack portable, and both the Saudi build-out and the UAE's own capacity pipeline become procurement options rather than gambles.
What to do now
- Put four dates in any 2027 capacity agreement with HUMAIN or a regional operator: substation energisation, hall handover, rack installation, benchmark acceptance. Tie payments to them, and record design rack density, PUE and curtailment terms in the same schedule.
- Stand up FastLLM Proxy as your single OpenAI-compatible endpoint in front of self-hosted GPU servers and hosted providers, set per-team monthly budgets with hard stops, and pin the go-ai-sdk version your services import so a backend swap stays a config change.
- Benchmark your two heaviest workloads under vLLM (https://github.com/vllm-project/vllm) or SGLang (https://github.com/sgl-project/sglang) on an AMD Instinct (ROCm) pool against an Nvidia (CUDA) pool before committing to one vendor stack. HUMAIN's backers include both AMD and Nvidia, so both paths will be options in this market.
- Rebuild your compute business case on this deal's yardstick: about $11.7M per MW of GPU IT load, and about $0.37 per watt for grid works. Compare buy, lease and reserved capacity over a 3 to 5 year refresh before you commit capex.